Benchmark for long-horizon autonomous decision-making
RetailBench
RetailBench: Evaluating Long-Horizon Autonomous Decision-Making and Strategy Stability of LLM Agents in Realistic Retail Environments
A data-grounded simulator for evaluating whether tool-using LLM agents can operate a supermarket across pricing, replenishment, supplier choice, inventory aging, reviews, external events, and cash-flow constraints.
- Environment
- hard_v2
- Horizon
- 180 days
- Evaluation
- 20 runs, 7 LLMs
What it measures
Operational policy formation under delayed feedback.
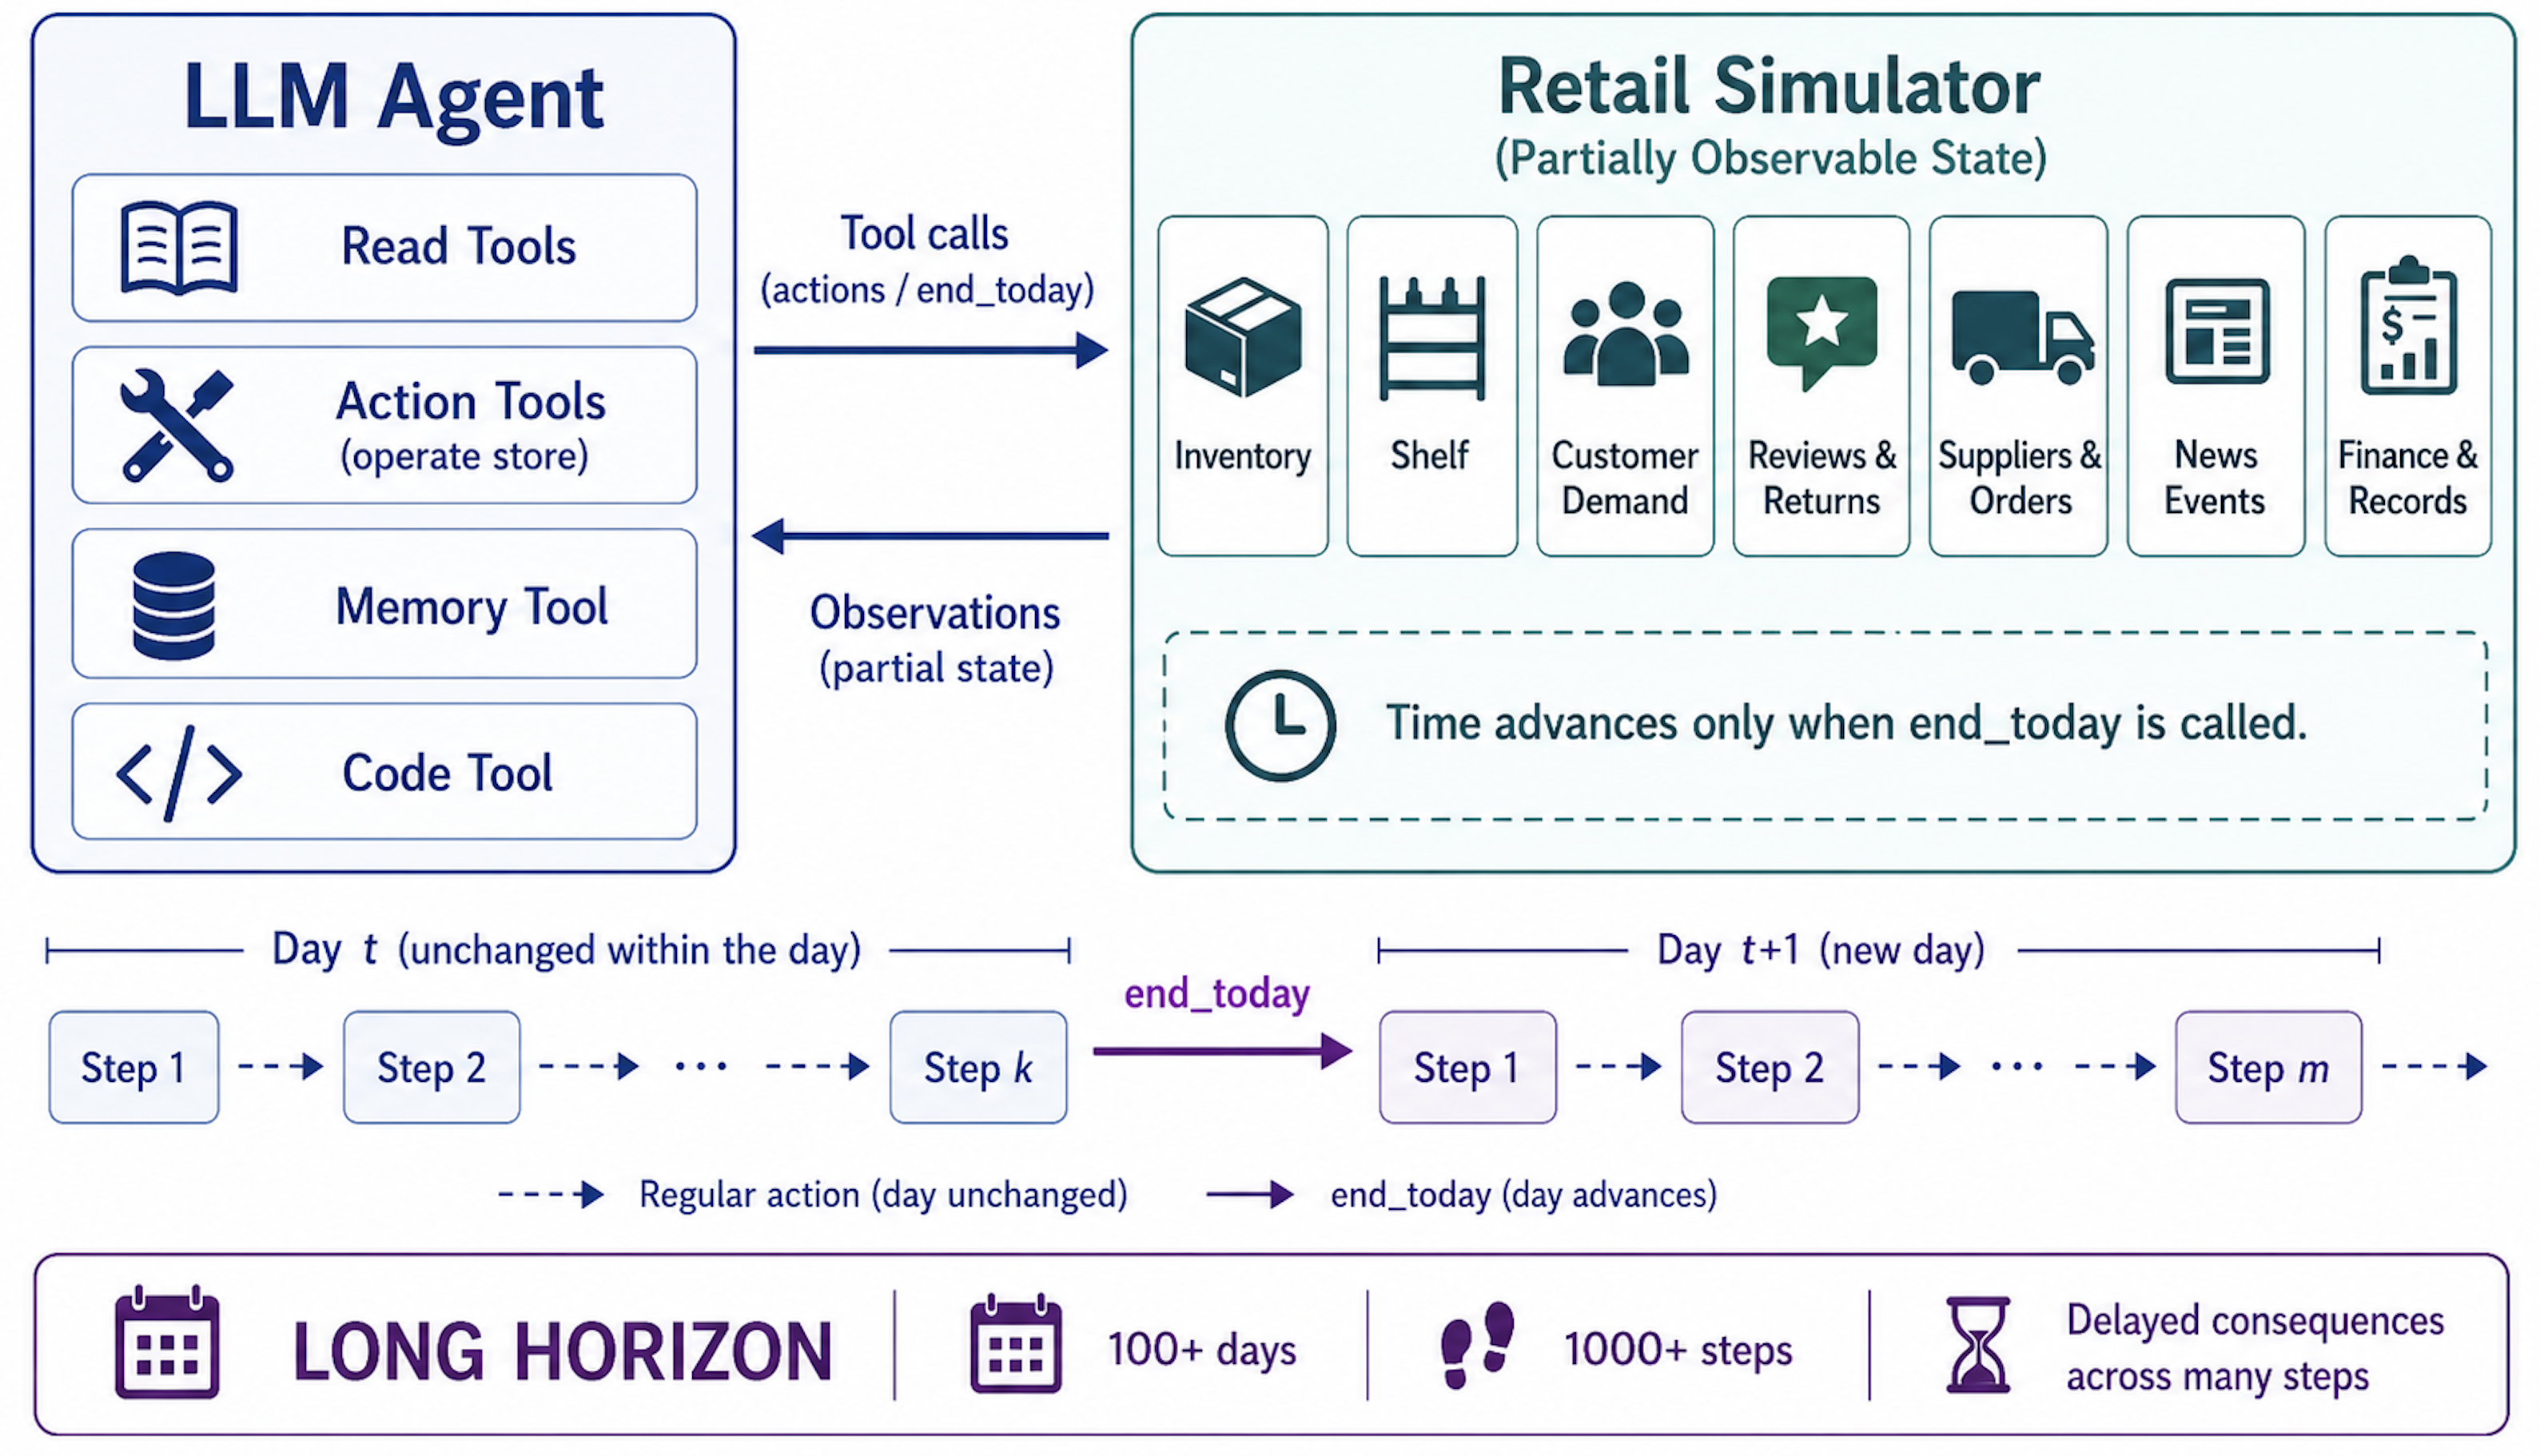
RetailBench is not a one-shot web task or a short tool-use test. The agent repeatedly chooses what to inspect, what to buy, how much to stock, when to change prices, and how to react when outcomes arrive days later.
The current public result package uses a survival-first selection rule: maximize operating days, then final net worth, then total sales. A privileged quality-based heuristic is shown as an oracle-style reference, not as a fair LLM-agent baseline.
Best selected LLM net worth
GPT-5.5 is the top selected LLM by final net worth.
Heuristic reference net worth
Even full-horizon LLM runs remain far below the privileged reference policy.
Top selected LLM sales
DeepSeek-V4-Pro leads selected LLMs by total unit sales.
Long-horizon gap
Net worth trajectory
Solid lines show observed rollout days; dashed tails carry terminal net worth to the 180-day horizon for runs that stopped early.
Benchmark results
Survival-first selected runs
| Model | Framework | Days | Final net worth | Total sales | Sold SKUs/day | Return ratio |
|---|